The key facts
- Irene Solaiman (Hugging Face): AI benchmarks are an 'evolving science'; the industry has not yet learned how to compare tests with each other.
- Reproducibility of evaluations depends on access to the model — open weights play an important role.
- Evaluation is shifting from the model to the whole system: the harness and the agent can give a weak model an advantage over a frontier model.
AI benchmarks are not yet a coherent science
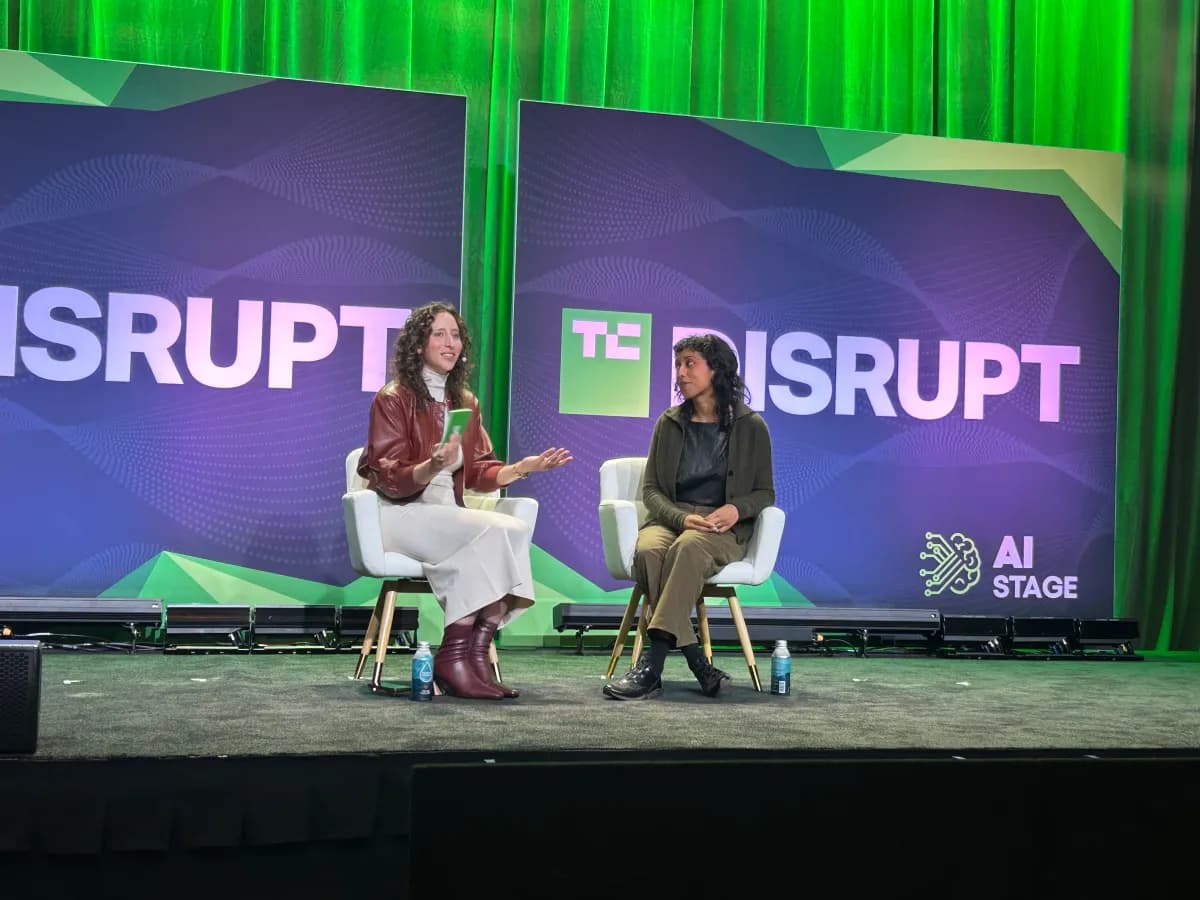
AI labs largely build their reputation on benchmarks — evaluations that are supposed to neutrally and accurately show which model is better. However, the methods behind these evaluations are complex and still taking shape, said Irene Solaiman, head of policy at Hugging Face, during a panel at TechCrunch Disrupt. According to her, for the industry to be able to rely on tests in the future, they need to become a more coherent science.
Trust and reproducibility
'Trust is a very loaded term,' Solaiman noted. The key question is whether evaluation results can be reproduced, and for that, sufficient access to the model itself is needed; here, she said, open weights play a big role. Reproducibility has long remained one of the most contentious aspects of benchmarking and the subject of significant disputes in the industry. In addition, in her assessment, tests are an 'evolving science,' and it is still unclear how to meaningfully compare them with one another.
Built-in evaluators and criticism of Anthropic's decision
Solaiman added that tests are 'quickly losing effectiveness,' and the evaluation ecosystem is underdeveloped: 'There is a hunger for an ecosystem of built-in evaluators, but the qualifications that define who is an effective evaluator and for which tasks require much greater standardization.' The idea of built-in evaluators — supposedly neutral third-party observers inside AI organizations — has gained popularity in recent months amid a series of safety incidents, one of which affected Hugging Face itself. Labs are promoting the third-party solution instead of active government regulation, but doubts about the neutrality and effectiveness of evaluators persist: Anthropic's decision to hire Accenture as its first evaluator drew notable criticism — some observers doubted that the consulting firm was qualified for such a task.
Evaluation is shifting from the model to the whole system
Evaluations are moving from testing the model itself to testing the entire system around it, including the harness and the agent. The harness — the tool through which the user interacts with the model — strongly influences results: a weak model with a good harness can easily outperform a frontier model, Solaiman noted. 'Agent evaluations are very complex and very expensive. We have more evaluations for models... there are fewer evaluations for harnesses, and we are developing better evaluations for the holistic agent — because that is where many people get value,' she said. In her conclusion, the evaluation space currently resembles a 'free-for-all dump,' and if benchmarking is to remain a useful tool, a more unified industry approach may be needed.